
Turn abandoned patents
into your own filing
into your own filing
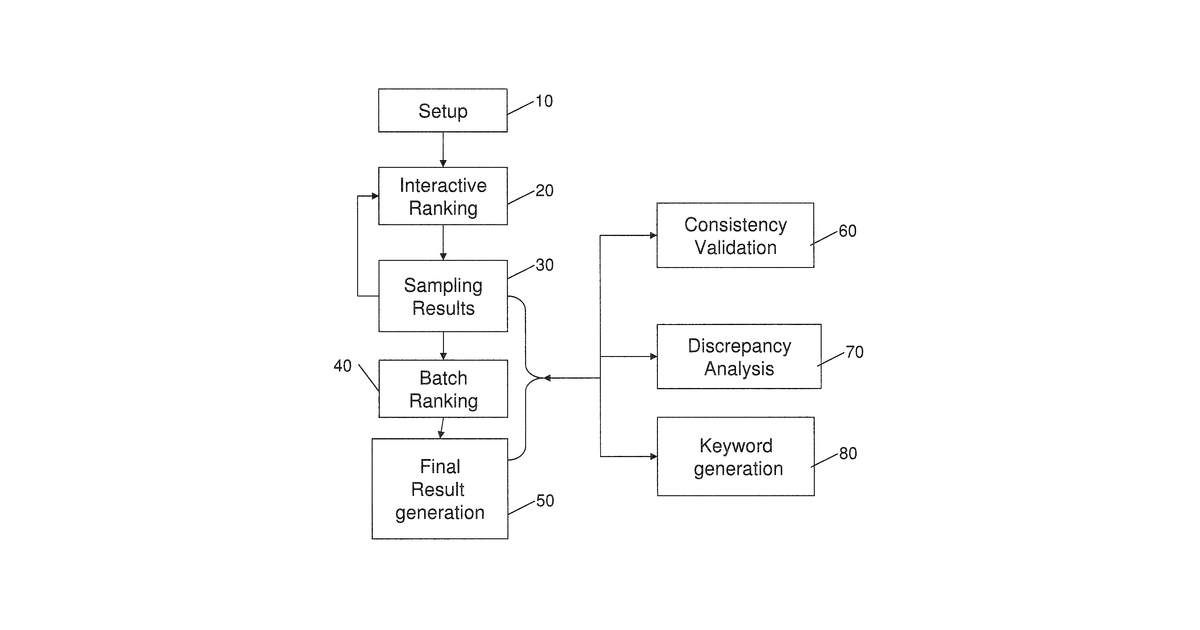
This invention describes a software-based method for checking how well a computer program categorizes digital documents. It works by selecting a small, random group of documents (a "control set") and using them to estimate how accurate the categorization process is. If the estimated accuracy isn't good enough, the system automatically adds more documents to the control set until it reaches a desired level of confidence in the evaluation.
Why it matters: Filed before the widespread adoption of deep learning and large language models, which have made text classification ubiquitous and complex. The need for robust, efficient evaluation of these advanced text classifiers is far greater now, and the computational resources to implement such an iterative validation method are readily available.
AI gives you a few directions you could take this. Pick one, and we check whether your version is different enough to patent, then write the filing.
Reinvent this with AI


