
Turn abandoned patents
into your own filing
into your own filing
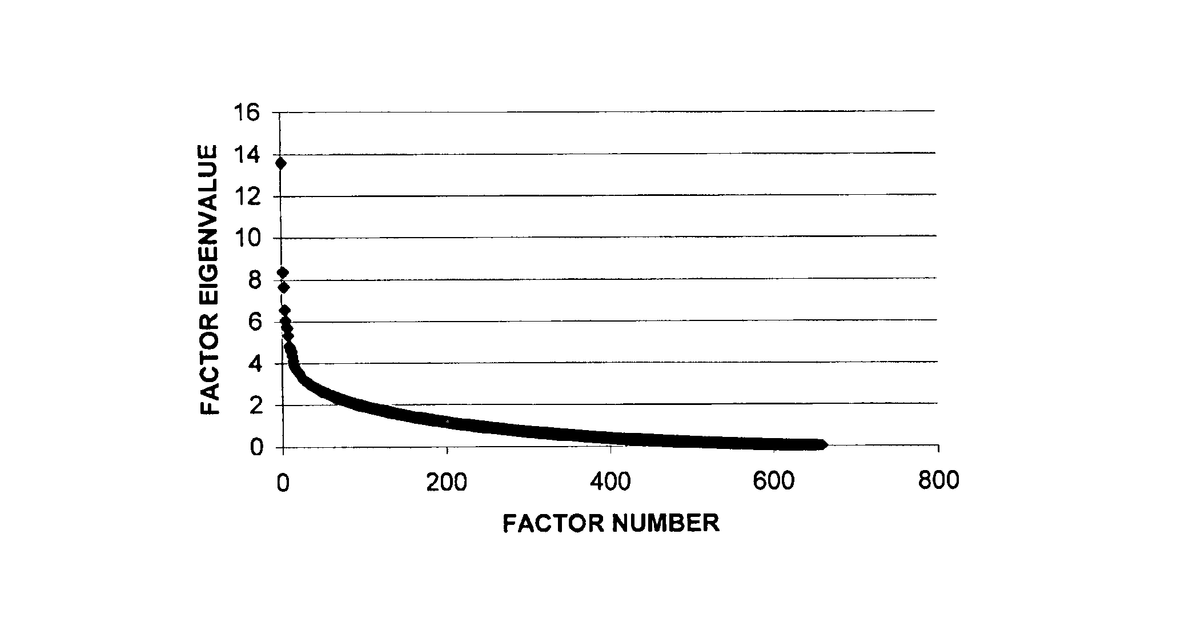
This invention describes a way to find specific information within a collection of documents. It works by first running a test search, then analyzing the results by looking at how often certain phrases appear and how they appear together. This analysis helps to refine the search, classify documents, and even identify important themes or relationships within the text. The claims specifically detail using a ratio to determine relevance based on how often a search term appears in relevant versus non-relevant documents.
Why it matters: Filed before the widespread adoption of advanced machine learning and large language models, the techniques described (like phrase frequency and co-occurrence analysis) were computationally intensive and limited in semantic understanding. Today, these tasks, including sophisticated document classification and query refinement, can be performed with far greater accuracy and scale using modern NLP tools and LLMs, making the core concepts much more powerful and accessible.
AI gives you a few directions you could take this. Pick one, and we check whether your version is different enough to patent, then write the filing.
Reinvent this with AI


