
Turn abandoned patents
into your own filing
into your own filing
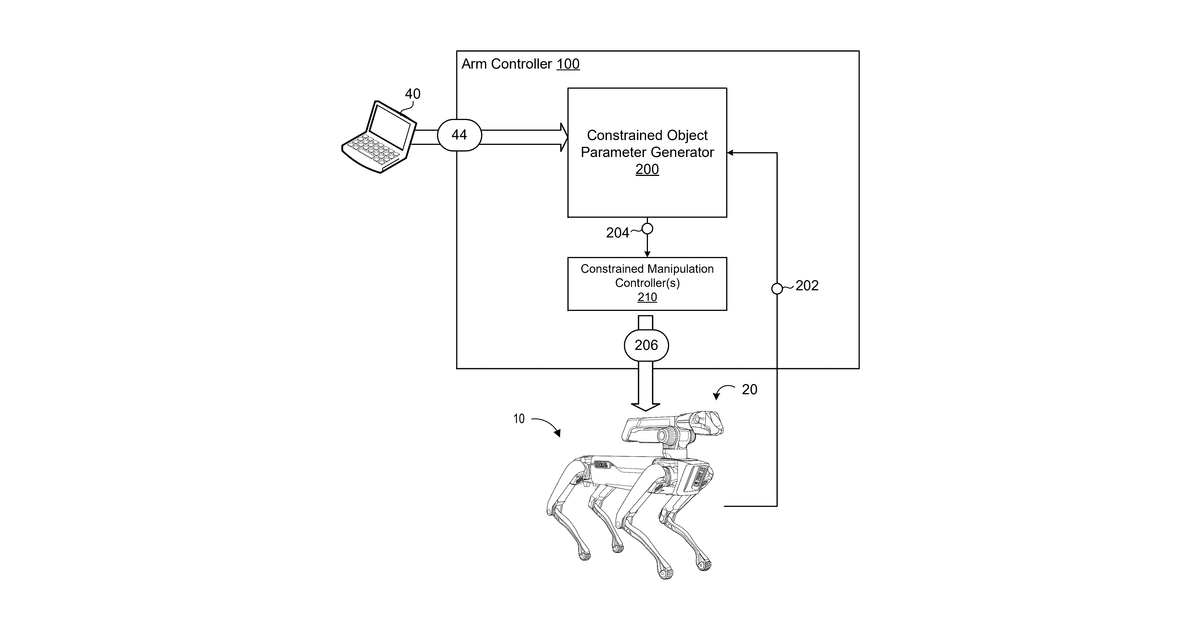
A robot uses its sensors to "see" a specific object that is fixed or can only move in limited ways, like a door handle or a lever. It then creates a detailed understanding (a "semantic model") of that object from what it sees. Based on this understanding and a request, the robot figures out exactly where and how its arm should grab or push the object, and then performs the action.
Why it matters: Since 2024, rapid advancements in vision-language models and foundation models for robotics have significantly improved the ability to generate detailed semantic models from perception data and translate them into precise robotic actions, making the core challenges more tractable.
AI gives you a few directions you could take this. Pick one, and we check whether your version is different enough to patent, then write the filing.
Reinvent this with AI


