
Turn abandoned patents
into your own filing
into your own filing
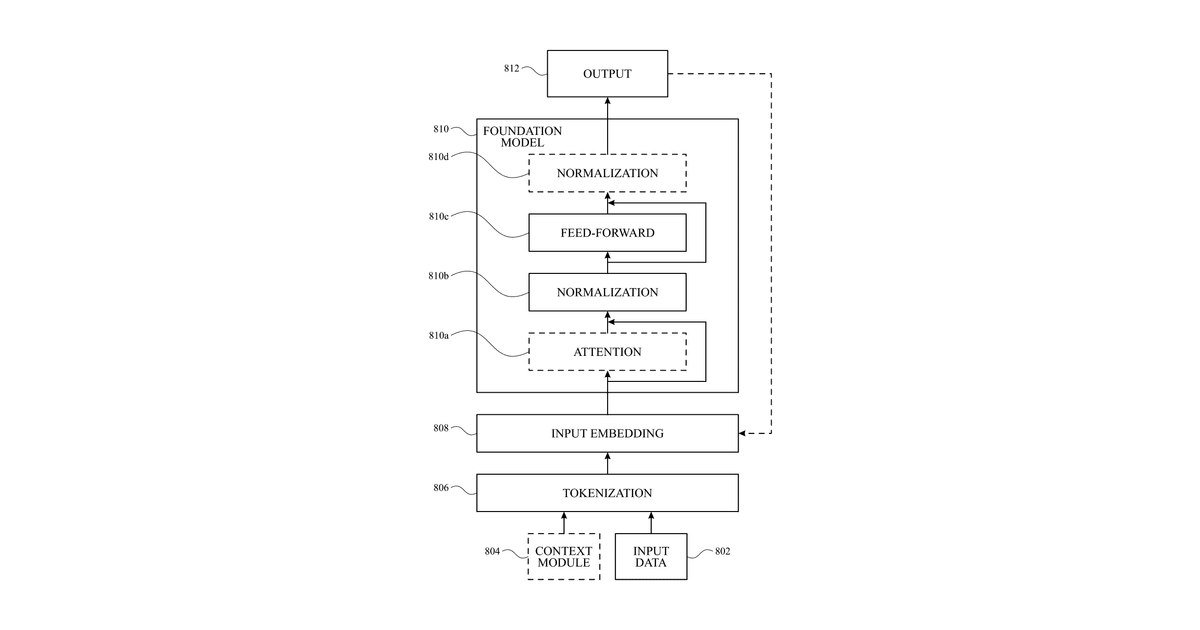
This invention describes a digital assistant that can understand its surroundings by looking at images. It takes two pictures, uses advanced AI models (called foundation models) to figure out what's in each picture, then combines that information to understand the overall scene. Based on this understanding, the assistant can then decide what task it needs to perform. The claims specifically narrow this to using foundation models trained on images and text to create these semantic descriptions.
Why it matters: Filed in 2024, the rapid advancements in multimodal foundation models since then have made the accurate semantic understanding of environments and subsequent task inference significantly more robust and accessible. The technology to reliably perform the described image analysis and task determination has matured considerably.
AI gives you a few directions you could take this. Pick one, and we check whether your version is different enough to patent, then write the filing.
Reinvent this with AI


