
Turn abandoned patents
into your own filing
into your own filing
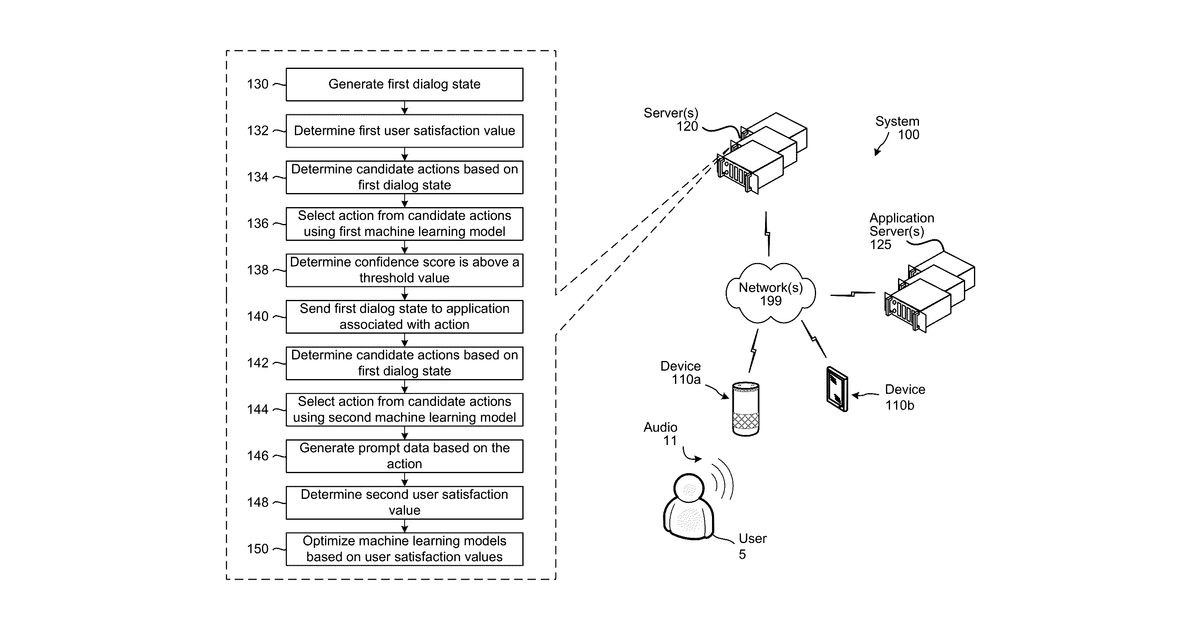
This invention describes a way for speech-controlled systems to make decisions that improve how happy users are over time, even if it means a less satisfying interaction in the short term. It does this by using trained computer models that learn from user history and profiles to pick the best action or response. The claims specifically focus on using these trained models to process user input and history to generate responses through different system components.
Why it matters: The rapid advancements in large language models (LLMs) and reinforcement learning from human feedback (RLHF) since 2024 make training models for nuanced, long-term user satisfaction optimization significantly more effective and accessible.
AI gives you a few directions you could take this. Pick one, and we check whether your version is different enough to patent, then write the filing.
Reinvent this with AI


