
Turn abandoned patents
into your own filing
into your own filing
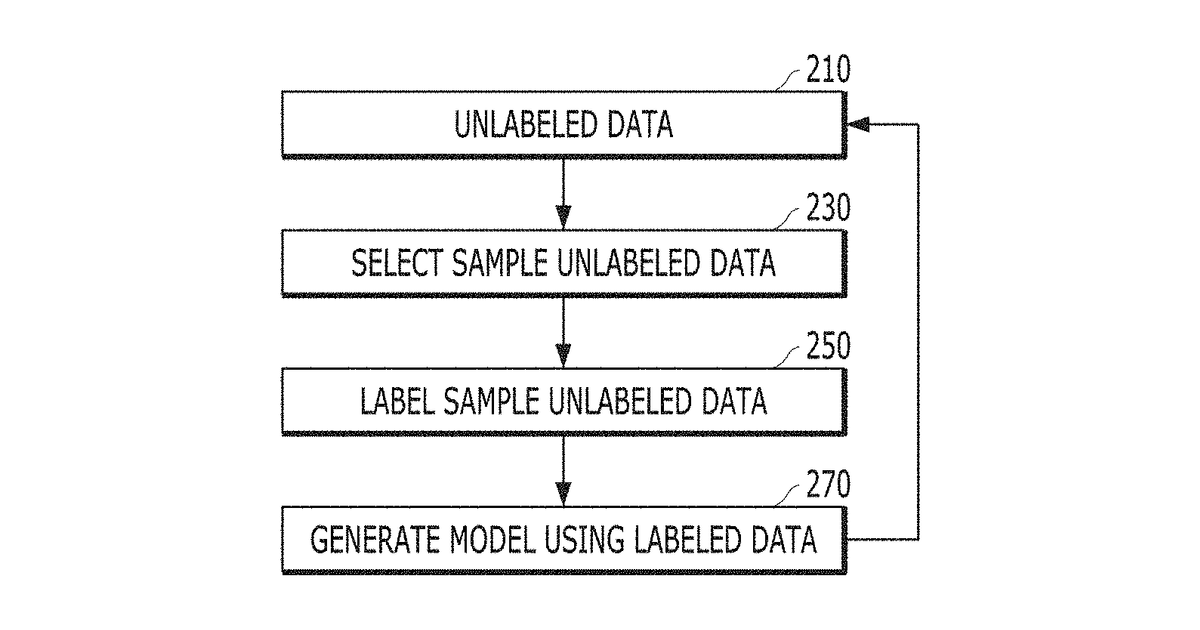
This invention describes a computer program that helps manage large sets of training data for machine learning. It works by looking at how unsure a computer model is about labeling certain data points and how similar those data points are to others. Based on these two factors, it intelligently picks the most useful data to be labeled, and then uses that newly labeled data to improve the computer model, specifically a classification model.
Why it matters: The explosion of large-scale AI models since 2022 has dramatically increased the demand for efficient, high-quality data labeling. This method directly addresses the critical bottleneck of managing vast datasets and optimizing labeling efforts for increasingly complex machine learning systems.
AI gives you a few directions you could take this. Pick one, and we check whether your version is different enough to patent, then write the filing.
Reinvent this with AI


