
Turn abandoned patents
into your own filing
into your own filing
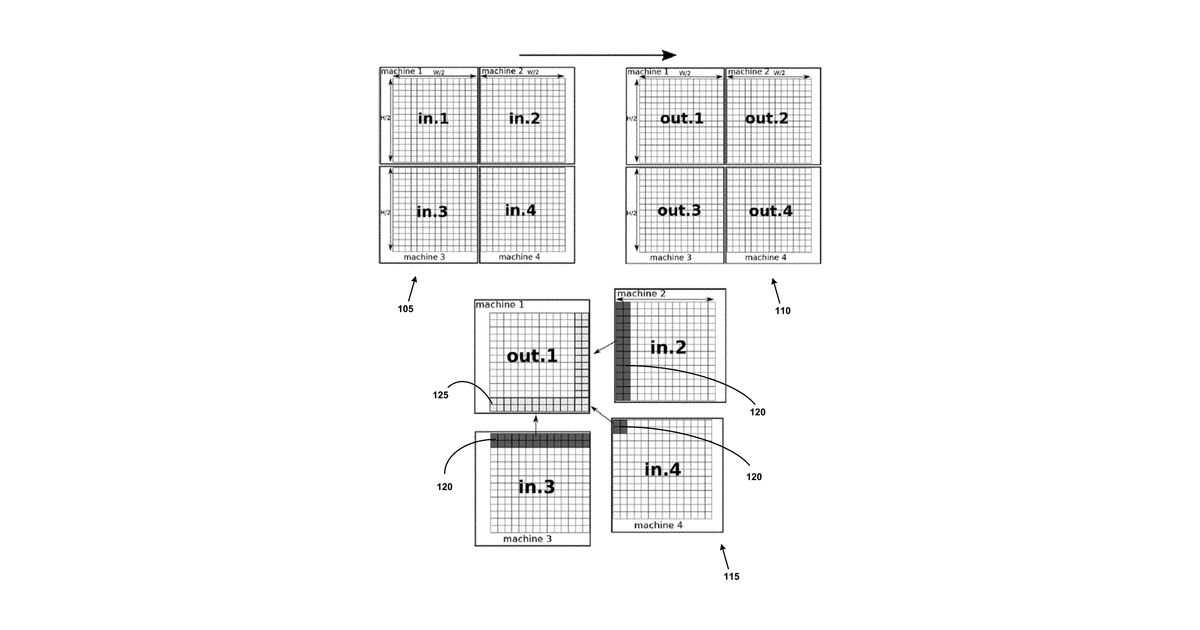
This invention describes a method to train large neural networks more efficiently by saving computer memory. It works by discarding temporary calculation data immediately after a network part finishes its initial pass, then re-calculating it on demand for fine-tuning. This approach is especially useful for distributed networks where different parts are processed by separate computers.
Why it matters: Since 2021, neural networks have grown dramatically in size, making memory bottlenecks a critical challenge for training. Modern distributed training frameworks have also matured, making the implementation of memory-saving techniques like re-computation across different computing units more feasible and impactful than ever before.
AI gives you a few directions you could take this. Pick one, and we check whether your version is different enough to patent, then write the filing.
Reinvent this with AI


