
Turn abandoned patents
into your own filing
into your own filing
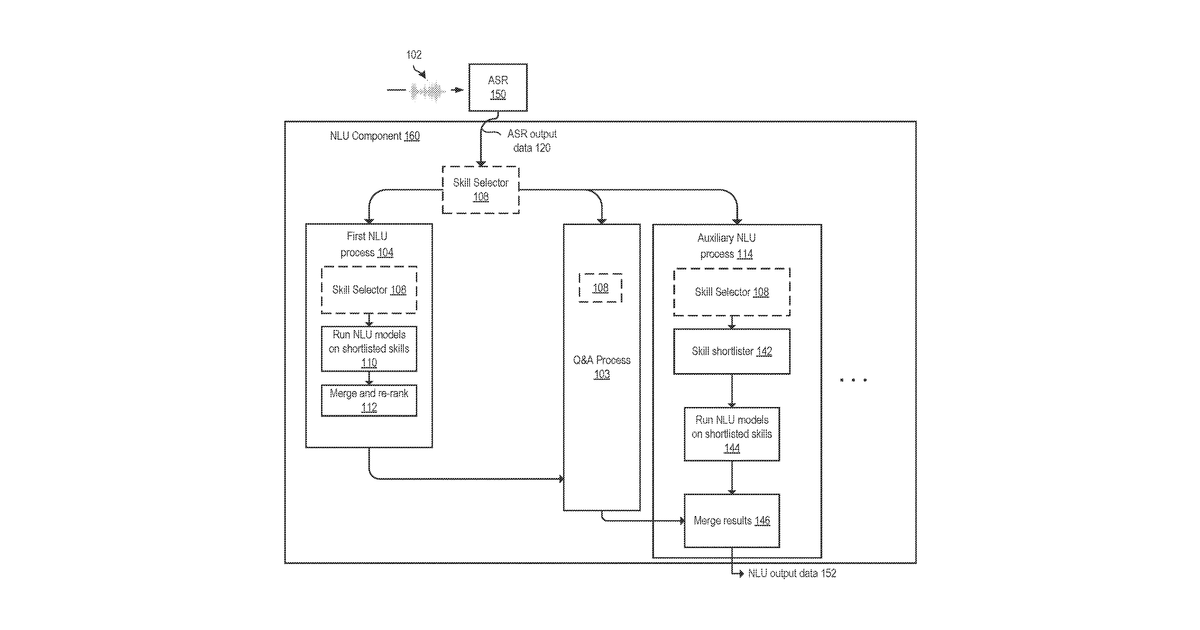
This invention describes a system designed to speed up natural language processing, such as understanding spoken commands. When a natural language input is received, it's first converted into text. The system then checks a memory (a cache) to see if it has processed a similar input before. If a match is found, it retrieves a previously identified 'skill' or context, which helps it quickly determine the intent of the current input without needing to perform a full, complex analysis. The claims specifically focus on using this cached skill to guide the interpretation of the input.
Why it matters: The widespread adoption of large, computationally expensive language models (LLMs) since 2022 makes inference reduction more critical. Modern embedding models, often derived from LLMs, significantly enhance the 'semantic similarity-based caching' central to this invention.
AI gives you a few directions you could take this. Pick one, and we check whether your version is different enough to patent, then write the filing.
Reinvent this with AI


