
Turn abandoned patents
into your own filing
into your own filing
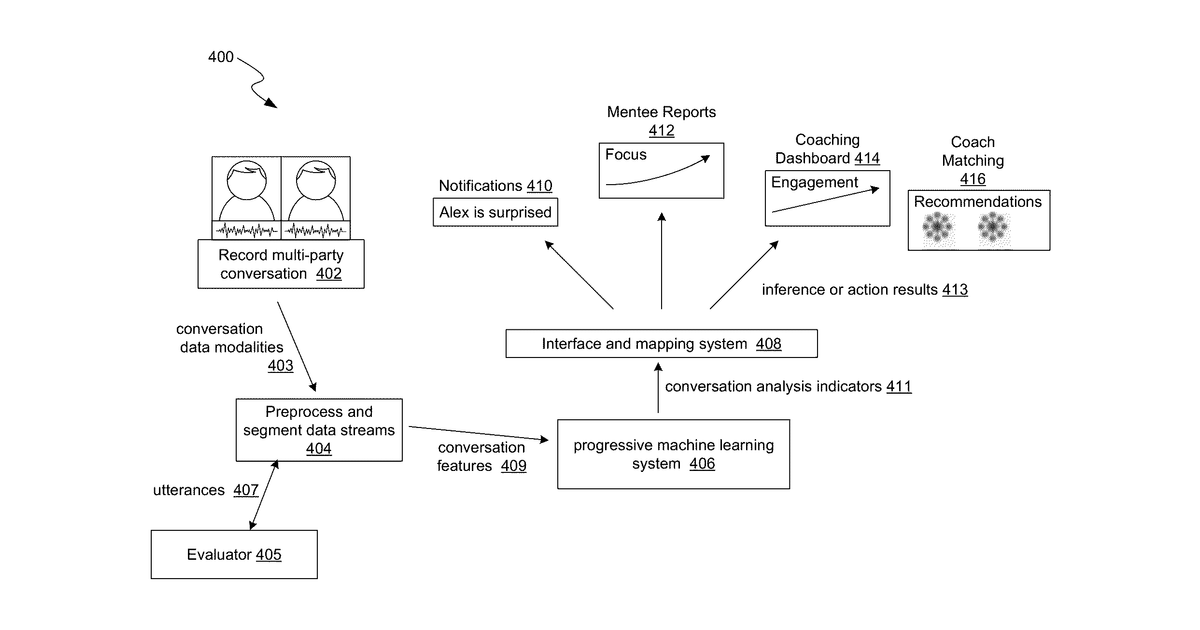
This invention describes a system for analyzing conversations involving multiple people. It works by taking recordings that include video, audio, and text of what each person says. An artificial intelligence system then processes each person's contribution using all three data types, and a second, sequential AI system uses these processed contributions, along with the conversation's history, to generate specific indicators about the conversation's dynamics. The claims specify processing individual speakers' contributions from the same time window and feeding them into a progressive system that builds on previous states.
Why it matters: Filed before multimodal large language models became widely capable. These models can now more effectively fuse video, acoustic, and text data, and handle sequential conversational context, making the core technical challenge more tractable.
AI gives you a few directions you could take this. Pick one, and we check whether your version is different enough to patent, then write the filing.
Reinvent this with AI


