
Turn abandoned patents
into your own filing
into your own filing
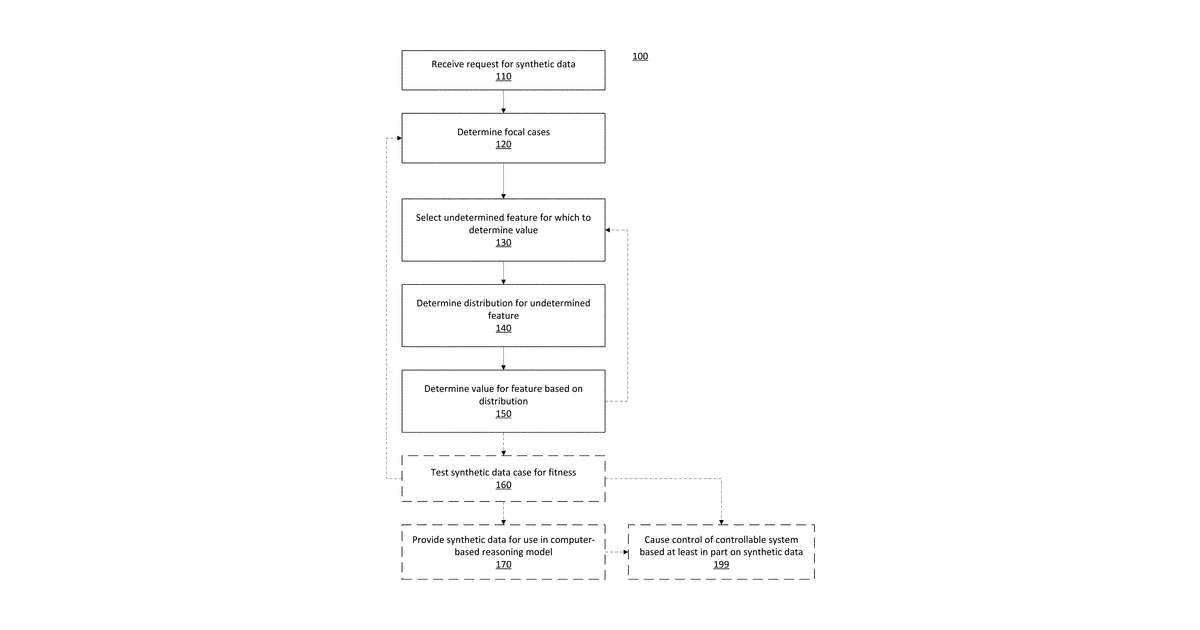
This invention describes a computer method for creating fake training data for AI systems. It works by picking a few key examples from existing data, then generating new data points based on those examples. A crucial step is checking if these newly generated data points are too similar to any existing data, often using a distance measurement, to ensure the new data adds genuine variety.
Why it matters: Since 2022, generative AI models like LLMs have made synthetic data generation much more powerful. This invention's focus on ensuring generated data isn't overly similar to existing data could be crucial for controlling these advanced models, preventing overfitting, and enhancing data diversity.
AI gives you a few directions you could take this. Pick one, and we check whether your version is different enough to patent, then write the filing.
Reinvent this with AI


