
Turn abandoned patents
into your own filing
into your own filing
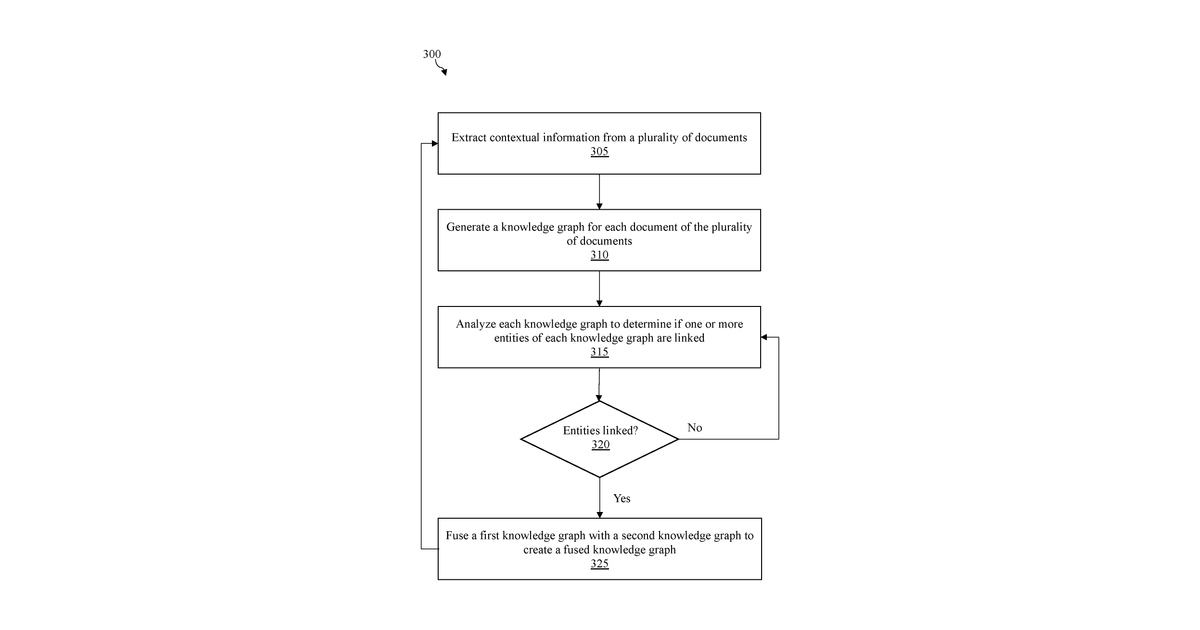
This invention describes a computer system that combines information from many different documents to create a single, larger knowledge base. It works by first identifying key facts and relationships within each document, creating a small "knowledge graph" for each one. Then, it looks for common facts or entities across these individual graphs and merges them together into one comprehensive graph, specifically using named-entity recognition on unstructured text and potentially a reading comprehension dataset like SQuAD.
Why it matters: Filed before the widespread adoption of powerful Large Language Models (LLMs). LLMs can now significantly simplify and improve the extraction of contextual information and the generation of knowledge graphs from unstructured text, making the initial steps of this invention much more robust and efficient.
AI gives you a few directions you could take this. Pick one, and we check whether your version is different enough to patent, then write the filing.
Reinvent this with AI


