
Turn abandoned patents
into your own filing
into your own filing
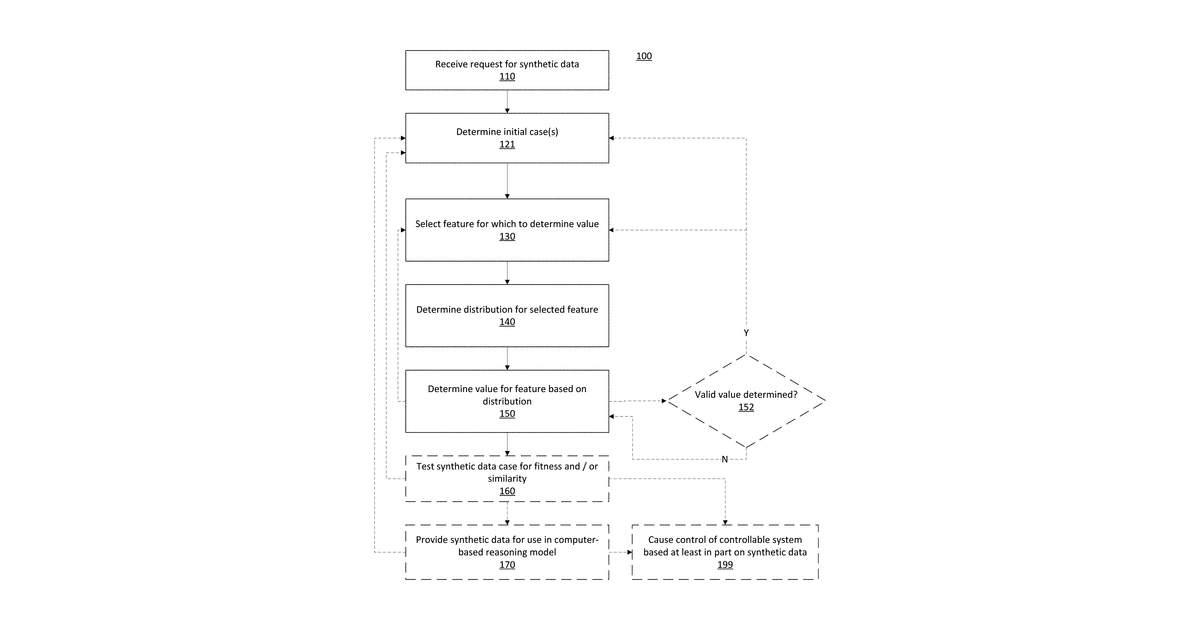
This invention describes a way to create fake data, called synthetic data, from real examples. It works by identifying key real data points, called focal cases, and then using them to generate new, artificial data. A crucial step is checking if the newly created synthetic data is too similar to the original real data using specific scores, like a prediction conviction score or a certainty score. If it's too similar, the synthetic data is adjusted or discarded to ensure it doesn't reveal information about the original data.
Why it matters: The demand for privacy-preserving data for AI/ML training has surged since 2020 due to stricter regulations and the exponential growth of complex models. This invention's method of generating synthetic data while checking for similarity to original data directly addresses these heightened privacy and data utility needs.
AI gives you a few directions you could take this. Pick one, and we check whether your version is different enough to patent, then write the filing.
Reinvent this with AI


