
Turn abandoned patents
into your own filing
into your own filing
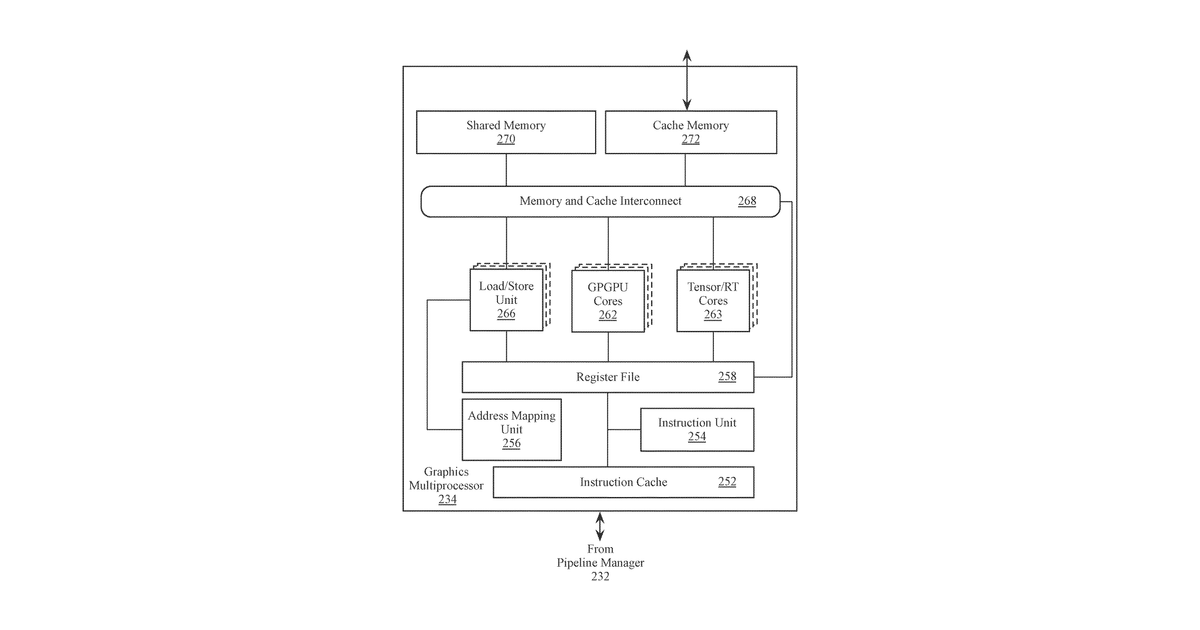
This invention describes a special kind of graphics processor designed to run neural networks more efficiently. It uses a shared memory system and a smart scheduler that understands individual neurons within the network. This allows different parts of the processor to work together on the neural network's calculations using a common memory pool.
Why it matters: Since 2021, the scale and complexity of neural networks, particularly large language models, have dramatically increased. This invention's focus on efficient GPU cache coherency for neural networks directly addresses the growing need for faster, more powerful AI processing hardware.
AI gives you a few directions you could take this. Pick one, and we check whether your version is different enough to patent, then write the filing.
Reinvent this with AI


