
Turn abandoned patents
into your own filing
into your own filing
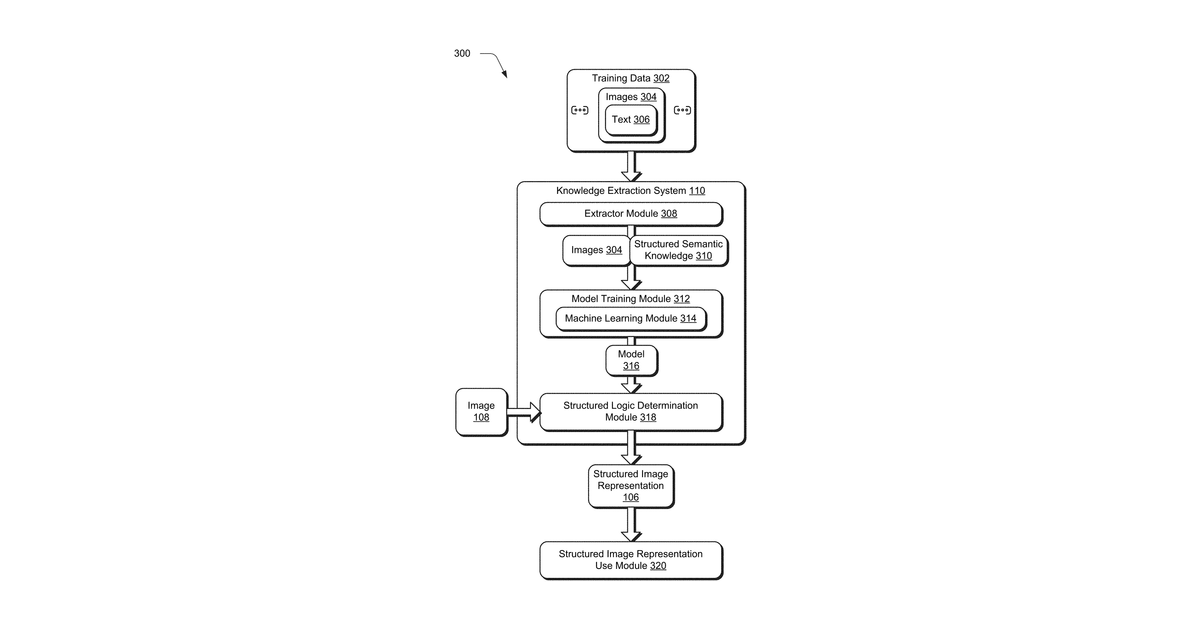
This invention describes a system that learns to understand and describe images automatically. It works by feeding a computer lots of images paired with text descriptions. The system analyzes the text to find key concepts and then trains a machine learning model to link these concepts to what's actually in the images. Once trained, this model can look at a new image and generate a detailed summary of its contents, even pinpointing specific objects within it using bounding boxes.
Why it matters: Filed before the widespread adoption of advanced multimodal AI and large language models, which now excel at the semantic analysis and image-text association described. Modern vision-language models can perform the core functions of extracting structured knowledge and generating descriptive summaries with significantly higher accuracy and less bespoke engineering than was possible in 2015.
AI gives you a few directions you could take this. Pick one, and we check whether your version is different enough to patent, then write the filing.
Reinvent this with AI


