
Turn abandoned patents
into your own filing
into your own filing
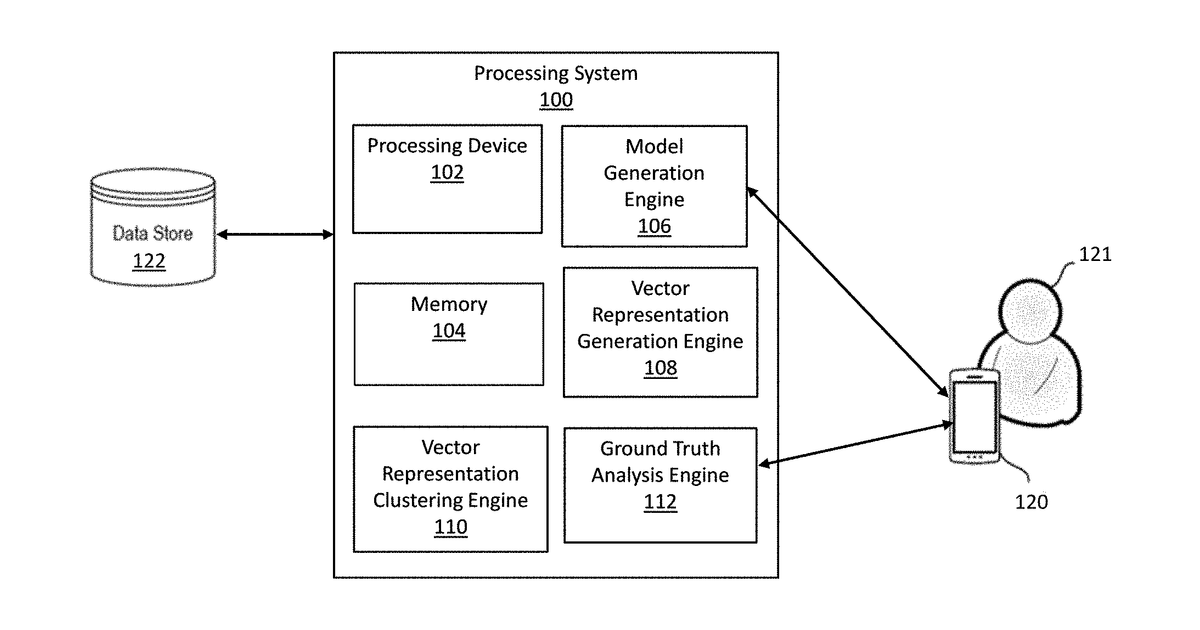
This invention describes a way to automatically find problems in the labeled data used to train artificial intelligence models. It works by taking your labeled data, training a model with it, and then converting each piece of data into a numerical representation. These representations are then grouped together, and the system identifies data points that don't fit well within their groups or are far from others, indicating they might be mislabeled, confusing, or simply unusual. The system then tells you which data points are problematic. The claims specifically mention using images as data and neural networks to create these numerical representations.
Why it matters: Filed in 2019, before the widespread adoption and scale of large foundation models. The immense datasets used for training modern AI models make manual ground truth validation impractical, increasing the value of automated anomaly detection for data quality.
AI gives you a few directions you could take this. Pick one, and we check whether your version is different enough to patent, then write the filing.
Reinvent this with AI


