
Turn abandoned patents
into your own filing
into your own filing
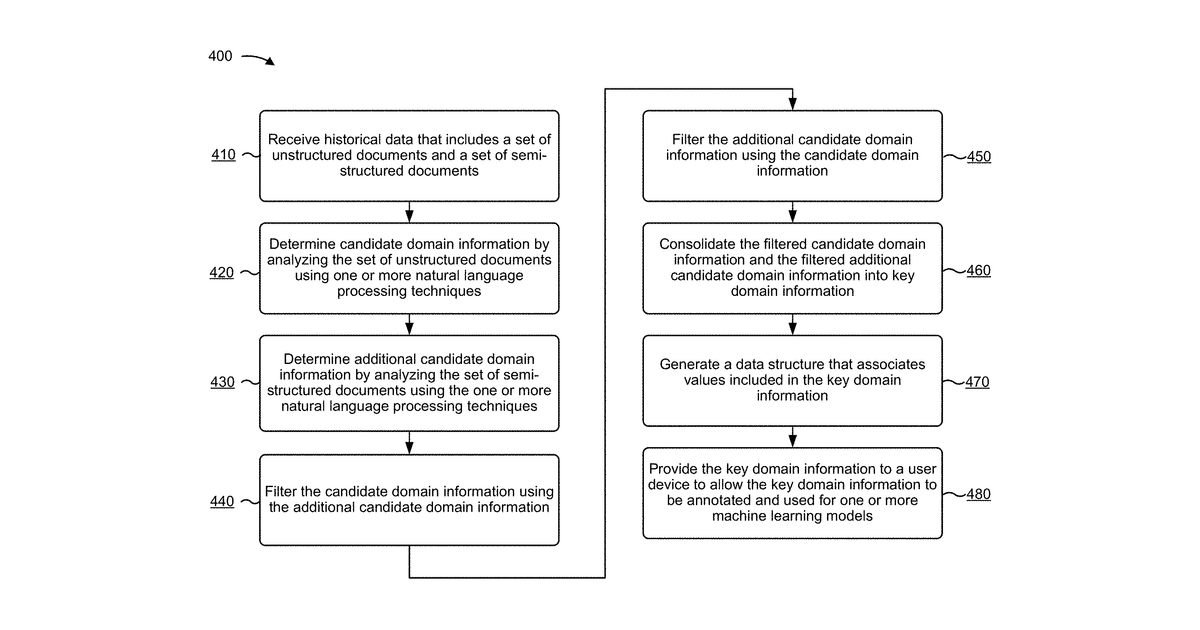
This invention describes a computer system that helps organizations identify important business terms from their documents to train artificial intelligence models. It works by first scanning all the organization's messy, unstructured text documents (like reports) to find potential key terms. Then, it cross-references these potential terms with more organized, semi-structured data (like spreadsheets or databases) to filter out irrelevant ones and confirm the truly important business-specific information. The final, refined list of key terms can then be used to build better AI.
Why it matters: Filed before the widespread adoption and capabilities of large language models (LLMs), the methods described for NLP and entity identification were cutting-edge in 2017. Today, advanced LLMs and AI techniques can significantly enhance the accuracy and automation of extracting, filtering, and consolidating domain information, making the core problem much more tractable and powerful to solve.
AI gives you a few directions you could take this. Pick one, and we check whether your version is different enough to patent, then write the filing.
Reinvent this with AI


