
Turn abandoned patents
into your own filing
into your own filing
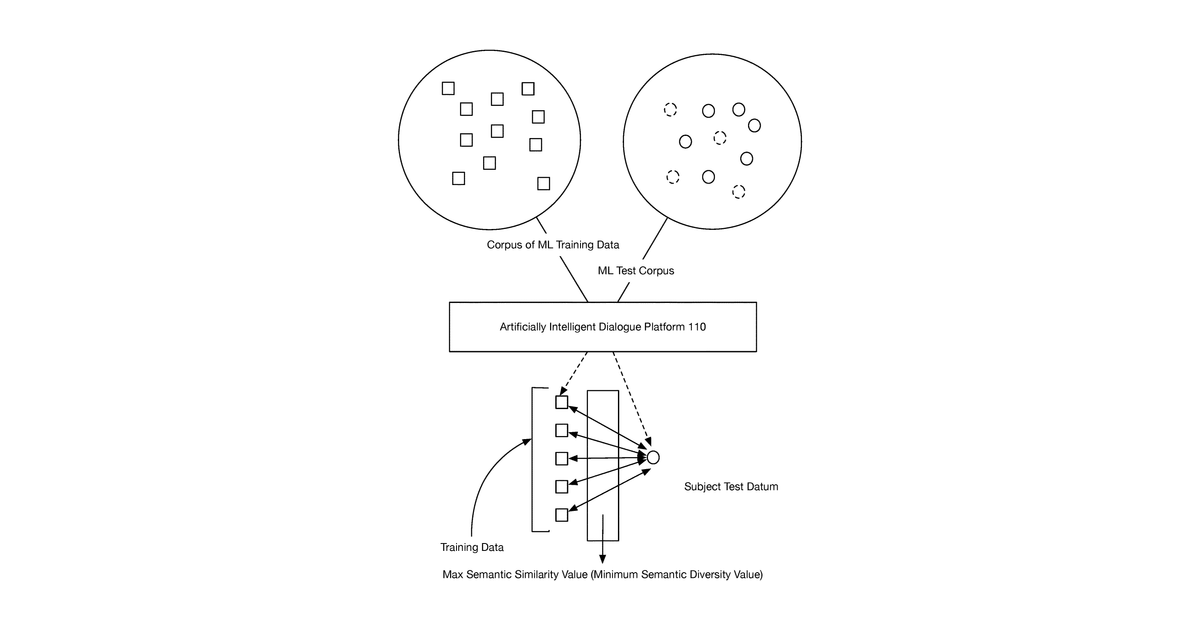
This invention describes a system for improving machine learning-based dialogue services, like chatbots. It works by first analyzing past user questions and commands to create a test set. Then, it gathers new raw training data from various sources. Before using this new data, the system checks its quality by measuring how well it covers different topics and how diverse it is. The system only uses this new data to train its machine learning models if the data meets a minimum quality standard for coverage.
Why it matters: Filed in 2019, before the widespread adoption of large language models (LLMs), this invention's focus on intelligently curating training data for dialogue systems is now even more critical. The exponential growth in LLM size and complexity has amplified the need for efficient, high-quality data acquisition and validation to improve performance and reduce training costs.
AI gives you a few directions you could take this. Pick one, and we check whether your version is different enough to patent, then write the filing.
Reinvent this with AI


