
Turn abandoned patents
into your own filing
into your own filing
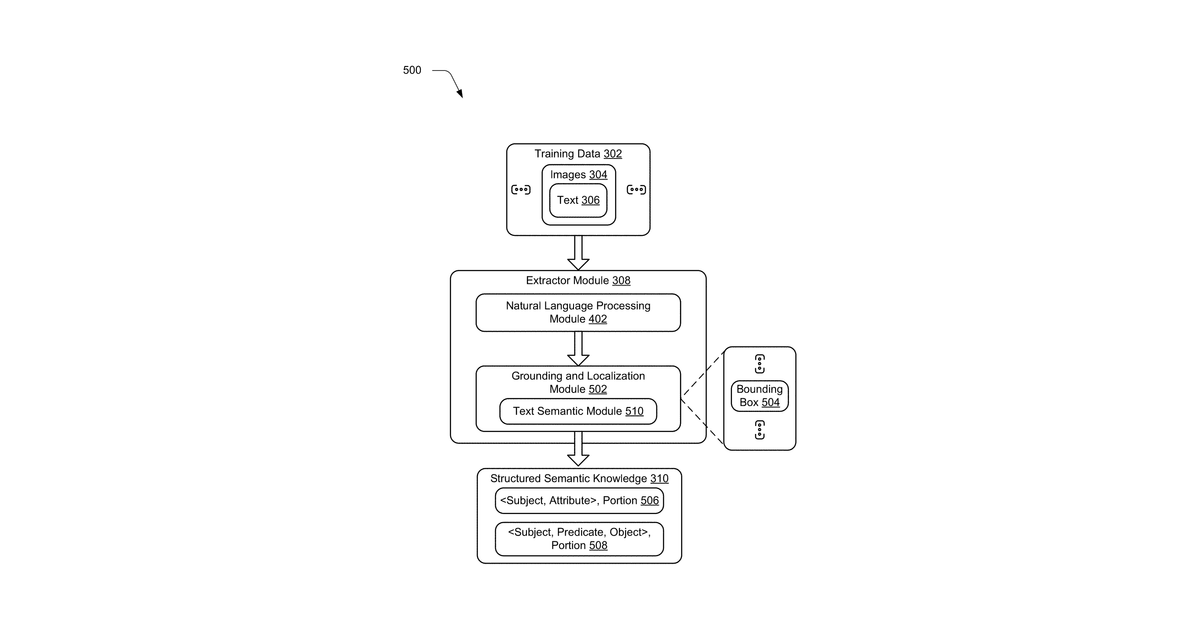
This invention describes a computer system that automatically understands what's happening in pictures. It learns by looking at many images paired with their descriptions, like captions or other text. From this learning, it builds a model that can then analyze new pictures and generate a detailed summary of the objects, their characteristics, and how they interact, all without needing human help. The system is specifically designed to learn from unstructured text like captions.
Why it matters: Filed before the rise of powerful multimodal AI and large language models. What required custom machine learning in 2015 can now be done more effectively with pre-trained vision-language models that excel at linking image content to free-form text descriptions.
AI gives you a few directions you could take this. Pick one, and we check whether your version is different enough to patent, then write the filing.
Reinvent this with AI


