
Turn abandoned patents
into your own filing
into your own filing
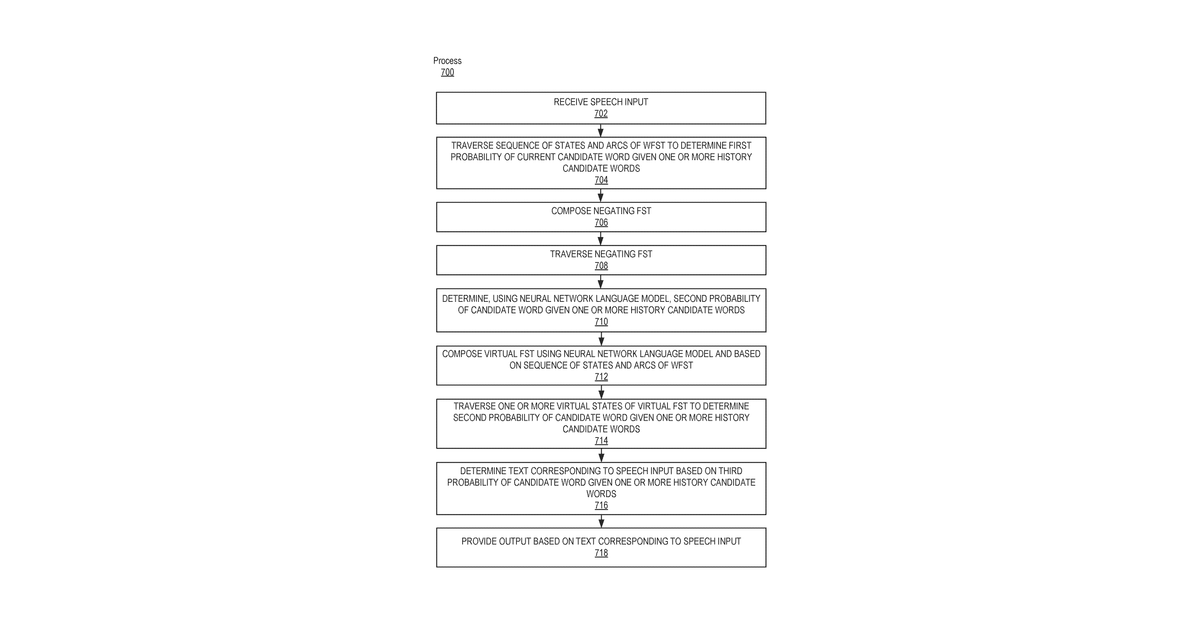
This invention describes a way to turn spoken words into text using computer software. It first uses a pre-defined language model to make an initial guess about the words being spoken and their likelihoods. Then, it applies a neural network to refine these guesses by creating a simplified, temporary language model where each step only allows for one specific next word, helping to pick the most accurate transcription.
Why it matters: Neural network language models have become vastly more powerful and efficient since 2018, potentially enhancing the accuracy and speed of this approach. This advancement could make the complex computations involved in composing and traversing the virtual FST more practical and effective.
AI gives you a few directions you could take this. Pick one, and we check whether your version is different enough to patent, then write the filing.
Reinvent this with AI


